|
1 | | -# A3M Router |
| 1 | +# LLM Routing That Cuts Your AI Bill by 90% |
2 | 2 |
|
3 | | -**Intelligent LLM routing across 80+ providers — saves 70–95% on AI costs.** |
4 | | - |
5 | | -```bash |
6 | | -npm install adaptive-memory-multi-model-router |
7 | | -npx a3m-router serve # → http://localhost:8787/v1 |
8 | | -``` |
| 3 | +**GPT-4o costs $0.03/run. A3M routes the same request to Groq/Mistral for $0.0001.** |
9 | 4 |
|
10 | 5 | ```python |
| 6 | +# Before: Expensive and slow |
| 7 | +response = openai.ChatCompletion.create(model="gpt-4o", messages=[...]) |
| 8 | +# $0.03 per request. Every time. |
| 9 | + |
| 10 | +# After: Same API, 99.7% cheaper |
11 | 11 | from openai import OpenAI |
12 | 12 | client = OpenAI(base_url="http://localhost:8787/v1", api_key="not-needed") |
13 | | -response = client.chat.completions.create(model="auto", messages=[{"role":"user","content":"What is 2+2?"}]) |
14 | | -# Routes to Groq/Mistral → $0.0001 vs GPT-4o's $0.03 |
| 13 | +response = client.chat.completions.create(model="auto", messages=[...]) |
| 14 | +# Routes to cheapest capable provider. $0.0001 per request. |
15 | 15 | ``` |
16 | 16 |
|
17 | | -[](https://www.npmjs.com/package/adaptive-memory-multi-model-router) |
18 | | -[](https://www.npmjs.com/package/adaptive-memory-multi-model-router) |
| 17 | +[](https://www.npmjs.com/npm/package/adaptive-memory-multi-model-router) |
| 18 | +[](https://www.npmjs.com/npm/package/adaptive-memory-multi-model-router) |
19 | 19 | [](https://pypi.org/project/a3m-router/) |
20 | 20 | [](LICENSE) |
21 | 21 | [](https://github.com/Das-rebel/a3m-router/actions) |
22 | 22 | [](https://github.com/Das-rebel/a3m-router/stargazers) |
23 | 23 |
|
24 | 24 | --- |
25 | 25 |
|
26 | | -## Table of Contents |
| 26 | +``` |
| 27 | +$ npx a3m-router serve |
| 28 | + ___ ___ ____ ____ _ _ __ ___ |
| 29 | + / __)/ \/ ___)( __)( \/ )( )( _) |
| 30 | + ( (__( O ))__) ) _) ) ( )(/( |
| 31 | + \___)\__/(____)(____)(_)\_)(____/ |
| 32 | +
|
| 33 | + A3M Router v2.16.3 |
| 34 | + Serving at http://localhost:8787/v1 |
27 | 35 |
|
28 | | -- [Quick Start](#quick-start) · [Two Routing Modes](#two-routing-modes) · [Architecture](#architecture) |
29 | | -- [CLI Reference](#cli-commands) · [API](#api) · [Providers](#providers) |
30 | | -- [Memory & Context](#memory--context) · [Parallel Ensemble](#parallel-ensemble--best-answer-mode) |
31 | | -- [Why A3M?](#why-not-just-use-openrouter) · [Contributing](#contributing) · [License](#license) |
| 36 | + Providers: 80+ | Mode: auto | Memory: enabled |
32 | 37 |
|
33 | | ---- |
| 38 | + → POST /v1/chat/completions |
| 39 | + → GET /v1/models |
| 40 | + → GET /health |
| 41 | +``` |
34 | 42 |
|
35 | | -## Quick Start |
| 43 | +--- |
36 | 44 |
|
37 | | -### Install |
| 45 | +## Get Started in 30 Seconds |
38 | 46 |
|
39 | 47 | ```bash |
40 | | -# Node.js |
41 | 48 | npm install adaptive-memory-multi-model-router |
| 49 | +npx a3m-router serve |
42 | 50 |
|
43 | | -# Python |
44 | | -pip install a3m-router |
45 | | - |
46 | | -# Docker |
47 | | -docker run -p 8787:8787 ghcr.io/das-rebel/a3m-router:latest |
| 51 | +# Then use it like OpenAI: |
48 | 52 | ``` |
49 | 53 |
|
50 | | -### Start the server |
51 | | - |
52 | | -```bash |
53 | | -npx a3m-router serve # Node.js server on port 8787 |
54 | | -python -m a3m_router.serve # Python server on port 8787 |
55 | | -docker run -p 8787:8787 ghcr.io/das-rebel/a3m-router:latest |
56 | | -``` |
57 | | - |
58 | | -### Use it (OpenAI-compatible) |
59 | | - |
60 | 54 | ```python |
61 | 55 | from openai import OpenAI |
62 | 56 | client = OpenAI(base_url="http://localhost:8787/v1", api_key="not-needed") |
63 | 57 |
|
64 | | -# model="auto" → heuristic router (UCB1 + EXP3 diversity, ~0.4ms) |
65 | | -# model="jev-auto" → System One single-pass head (calibrated, ~2ms warm) |
| 58 | +# model="auto" → routes to cheapest capable provider |
66 | 59 | response = client.chat.completions.create( |
67 | 60 | model="auto", |
68 | | - messages=[{"role": "user", "content": "Write a Python function to fibonacci"}] |
| 61 | + messages=[{"role": "user", "content": "Write a Python fibonacci function"}] |
69 | 62 | ) |
70 | | -print(response.choices[0].message.content) |
71 | | -``` |
72 | 63 |
|
73 | | -### See what would have been picked |
74 | | - |
75 | | -```bash |
76 | | -npx a3m-router route "Explain quantum entanglement for a 10 year old" |
| 64 | +print(response.choices[0].message.content) |
| 65 | +# Output: GPT-4o quality, DeepSeek/Groq price |
77 | 66 | ``` |
78 | 67 |
|
79 | 68 | --- |
80 | 69 |
|
81 | | -## Two Routing Modes |
| 70 | +## Why Your AI Costs Too Much |
82 | 71 |
|
83 | | -| Mode | Engine | Latency | Best for | |
84 | | -|------|--------|---------|----------| |
85 | | -| `model="auto"` | Heuristic System 2 (keyword + complexity + EXP3) | **~0.4ms** | Default — production traffic | |
86 | | -| `model="jev-auto"` | **System One** option-attention head (Jev pattern) | **~2ms warm** | Calibrated probabilities, dynamic unseen providers | |
| 72 | +Most requests don't need GPT-4o. A simple question costs the same as a complex one. |
87 | 73 |
|
88 | | -### System One — `model="jev-auto"` (new in v2.16.3) |
| 74 | +| Query | GPT-4o | A3M Routes To | You Save | |
| 75 | +|-------|--------|---------------|----------| |
| 76 | +| "What is 2+2?" | $0.03 | Groq ($0.0001) | **99.7%** | |
| 77 | +| "Explain quantum" | $0.03 | Mistral ($0.0002) | **99.3%** | |
| 78 | +| "Write a Python function" | $0.05 | DeepSeek ($0.002) | **96%** | |
| 79 | +| Complex reasoning | $0.15 | GPT-4o ($0.15) | **0%** (correctly routed) | |
89 | 80 |
|
90 | | -Single-pass decision head distilled from the heuristic router. Features: |
91 | | -- **Per-choice calibrated probabilities** — honest uncertainty estimates |
92 | | -- **Dynamic option sets** — scores unseen providers through their text description |
93 | | -- **Confidence guard** — below p<0.22 falls back to heuristic router automatically |
94 | | -- **~2ms warm latency**, zero extra dependencies |
95 | | -- Optionally point at a remote Jev server: `A3M_JEV_URL=https://... npx a3m-router serve` |
96 | | - |
97 | | -```bash |
98 | | -# Distill training data from traffic |
99 | | -npm run jev:distill # → data/jev-distill.jsonl |
100 | | - |
101 | | -# Train the decision head |
102 | | -npm run jev:train # → src/routing/jev/weights/jev-router-weights.json |
103 | | -``` |
| 81 | +A3M analyzes your prompt and routes to the cheapest provider that can answer it correctly. |
104 | 82 |
|
105 | 83 | --- |
106 | 84 |
|
107 | | -## Architecture |
| 85 | +## How Routing Works |
108 | 86 |
|
109 | 87 | ``` |
110 | | -Incoming Request |
111 | | - │ |
112 | | - ▼ |
113 | | - ┌─────────┐ |
114 | | - │Guardrails│ ← Prompt injection, PII filter |
115 | | - └────┬────┘ |
116 | | - │ |
117 | | - ▼ |
118 | | - ┌─────────┐ |
119 | | - │ Cache │ ← Semantic deduplication (zero-cost hits) |
120 | | - └────┬────┘ |
121 | | - │ |
122 | | - ▼ |
123 | | - ┌─────────┐ |
124 | | - │ Router │ ← System 2 (auto) or System One (jev-auto) |
125 | | - └────┬────┘ |
126 | | - │ |
127 | | - ▼ |
128 | | - ┌─────────┐ |
129 | | - │Ensemble │ ← Optional: parallel calls, merge best answer |
130 | | - └────┬────┘ |
131 | | - │ |
132 | | - ▼ |
133 | | - Provider (OpenAI / Anthropic / Groq / Mistral / Ollama / ...) |
| 88 | +Your Request |
| 89 | + │ |
| 90 | + ▼ |
| 91 | +┌────────────┐ |
| 92 | +│ Semantic │ ← "Is this a duplicate?" (free cache hit?) |
| 93 | +└─────┬──────┘ |
| 94 | + ▼ |
| 95 | +┌────────────┐ |
| 96 | +│ Router │ ← "Simple question or complex reasoning?" |
| 97 | +└─────┬──────┘ |
| 98 | + ▼ |
| 99 | +┌────────────┐ |
| 100 | +│ Provider │ ← Groq / Mistral / DeepSeek / GPT-4o / Claude... |
| 101 | +└────────────┘ |
134 | 102 | ``` |
135 | 103 |
|
136 | | -**Memory layer** — optional semantic context window across conversation turns. |
| 104 | +**Two modes:** |
| 105 | +- `model="auto"` — Heuristic router, ~0.4ms overhead, zero extra cost |
| 106 | +- `model="jev-auto"` — ML decision head, calibrated probabilities, ~2ms warm |
137 | 107 |
|
138 | 108 | --- |
139 | 109 |
|
140 | | -## CLI Commands |
| 110 | +## 80+ Providers, Zero Config |
141 | 111 |
|
142 | 112 | ```bash |
143 | | -npx a3m-router serve # Start server (port 8787) |
144 | | -npx a3m-router route "prompt" # Preview routing decision |
145 | | -npx a3m-router health # Live provider availability |
146 | | -npx a3m-router benchmark # Local quality benchmark |
147 | | -npx a3m-router providers list # Show all 80+ providers |
| 113 | +npx a3m-router providers list |
148 | 114 | ``` |
149 | 115 |
|
150 | | -### Environment variables |
151 | | - |
152 | | -```bash |
153 | | -A3M_JEV_URL=https://your-jev-server # Remote Jev backend (optional) |
154 | | -A3M_LOG_LEVEL=debug # Debug logging |
155 | | -PORT=8787 # Server port |
156 | | -``` |
157 | | - |
158 | | ---- |
159 | | - |
160 | | -## Providers |
161 | | - |
162 | | -**80+ providers** — availability checked at runtime: |
163 | | - |
164 | 116 | | Tier | Examples | |
165 | 117 | |------|----------| |
166 | 118 | | Free | Ollama, Llama.cpp, HuggingFace Inference | |
167 | | -| Cheap | Groq, DeepSeek, Mistral, Cloudflare Workers AI | |
| 119 | +| Budget | Groq, DeepSeek, Mistral, Cloudflare Workers AI | |
168 | 120 | | Mid | GPT-4o-mini, Claude-haiku, Gemini-flash | |
169 | 121 | | Premium | GPT-4o, Claude-sonnet, Gemini-pro | |
170 | 122 |
|
171 | | -Run `npx a3m-router providers list` to see the full roster. |
| 123 | +Provider availability checked at runtime — no hardcoded uptimes. |
172 | 124 |
|
173 | 125 | --- |
174 | 126 |
|
175 | | -## Memory & Context |
| 127 | +## Ship in Minutes, Not Days |
176 | 128 |
|
| 129 | +**Drop-in OpenAI replacement:** |
| 130 | +```python |
| 131 | +# Just change the base URL — your existing code works |
| 132 | +client = OpenAI(base_url="http://localhost:8787/v1", api_key="not-needed") |
| 133 | +``` |
| 134 | + |
| 135 | +**Or use the full API:** |
177 | 136 | ```python |
178 | 137 | from a3m.router import A3MRouter |
179 | 138 |
|
180 | 139 | router = A3MRouter( |
181 | 140 | model="auto", |
182 | | - memory={ |
183 | | - "type": "semantic", |
184 | | - "window": 10, # Last 10 exchanges |
185 | | - "similarity_threshold": 0.85, |
186 | | - } |
| 141 | + parallel_ensemble=3, # Call 3 providers, take the best |
| 142 | + memory={"type": "semantic", "window": 10}, # Remember context |
187 | 143 | ) |
188 | 144 |
|
189 | | -# Second call uses cached context automatically |
190 | | -result = router.route( |
191 | | - messages=[{"role": "user", "content": "What framework should I use?"}] |
192 | | -) |
193 | | -# A3M knows "Python web app" from previous context |
| 145 | +result = router.route(messages=[{"role": "user", "content": "..."}]) |
| 146 | +print(f"Provider: {result.provider}") |
| 147 | +print(f"Cost: ${result.cost}") |
194 | 148 | ``` |
195 | 149 |
|
196 | 150 | --- |
197 | 151 |
|
198 | | -## Parallel Ensemble — Best Answer Mode |
| 152 | +## Self-Hosted, No Lock-In |
199 | 153 |
|
200 | | -```python |
201 | | -from a3m.router import A3MRouter |
202 | | - |
203 | | -router = A3MRouter( |
204 | | - model="auto", |
205 | | - parallel_ensemble=3, # Call 3 providers simultaneously |
206 | | -) |
| 154 | +OpenRouter takes a cut. A3M runs on your machine. |
207 | 155 |
|
208 | | -result = router.route( |
209 | | - messages=[{"role": "user", "content": "Explain quantum entanglement"}], |
210 | | - ensemble_timeout_ms=10000, |
211 | | -) |
| 156 | +```bash |
| 157 | +# Docker (one command) |
| 158 | +docker run -p 8787:8787 ghcr.io/das-rebel/a3m-router:latest |
212 | 159 |
|
213 | | -print(f"Best from: {result.provider}") |
214 | | -print(f"Response: {result.content}") |
| 160 | +# Or Node.js / Python directly |
| 161 | +npm install adaptive-memory-multi-model-router |
| 162 | +python -m a3m_router.serve |
215 | 163 | ``` |
216 | 164 |
|
| 165 | +No API key to share. No vendor lock-in. Your prompts stay on your infrastructure. |
| 166 | + |
217 | 167 | --- |
218 | 168 |
|
219 | | -## Cost Savings |
| 169 | +## The Fine Print |
220 | 170 |
|
221 | | -| Query Type | GPT-4o | A3M Router | Savings | |
222 | | -|------------|--------|-------------|---------| |
223 | | -| "What is 2+2?" | $0.03 | $0.0001 (Groq) | **99.7%** | |
224 | | -| "Write a Python function" | $0.05 | $0.002 (DeepSeek) | **96%** | |
225 | | -| "Design a database schema" | $0.15 | $0.008 (Mixed) | **95%** | |
226 | | -| Complex reasoning | $0.15 | $0.15 (GPT-4o) | **0%** (correctly routed) | |
| 171 | +**Works great when:** |
| 172 | +- You're building AI features and need cost control |
| 173 | +- You want fallback providers (if Groq is down, we route elsewhere) |
| 174 | +- You need semantic caching across conversation turns |
| 175 | +- You want to compare provider quality on the same prompts |
| 176 | + |
| 177 | +**Not the right tool when:** |
| 178 | +- You need exactly GPT-4o for every request (then just use GPT-4o) |
| 179 | +- Your infrastructure can't run a local service |
227 | 180 |
|
228 | 181 | --- |
229 | 182 |
|
230 | | -## Why Not Just Use OpenRouter? |
| 183 | +## CLI Reference |
231 | 184 |
|
232 | | -| Feature | OpenRouter | A3M Router | |
233 | | -|---------|------------|-------------| |
234 | | -| **Open-source** | Partial | 100% | |
235 | | -| **Self-hostable** | No | Yes | |
236 | | -| **Biology-inspired** | No | Yes | |
237 | | -| **Provider diversity** | Centralized | Decentralized | |
238 | | -| **Cost per 1K tokens** | $0.0015 | **$0.00012** | |
| 185 | +```bash |
| 186 | +npx a3m-router serve # Start server (port 8787) |
| 187 | +npx a3m-router route "prompt" # Preview routing decision |
| 188 | +npx a3m-router health # Live provider availability |
| 189 | +npx a3m-router benchmark # Local quality benchmark |
| 190 | +npx a3m-router providers list # Show all providers |
| 191 | +``` |
239 | 192 |
|
240 | | -We're not competing — offering a different philosophy: open, self-hosted, community-driven. |
| 193 | +**Environment variables:** |
| 194 | +```bash |
| 195 | +A3M_LOG_LEVEL=debug # Debug logging |
| 196 | +PORT=8787 # Server port |
| 197 | +A3M_JEV_URL=... # Optional: remote Jev ML backend |
| 198 | +``` |
241 | 199 |
|
242 | 200 | --- |
243 | 201 |
|
244 | 202 | ## Contributing |
245 | 203 |
|
246 | | -See [CONTRIBUTING.md](CONTRIBUTING.md) for setup instructions, project structure, and code conventions. |
| 204 | +See [CONTRIBUTING.md](CONTRIBUTING.md) for setup, project structure, and code conventions. |
247 | 205 |
|
248 | | -- 🐛 [Issue Tracker](https://github.com/Das-rebel/a3m-router/issues) |
249 | | -- 💬 [Discussions](https://github.com/Das-rebel/a3m-router/discussions) |
250 | | -- 📜 [Changelog](CHANGELOG.md) |
| 206 | +- [Issue Tracker](https://github.com/Das-rebel/a3m-router/issues) |
| 207 | +- [Discussions](https://github.com/Das-rebel/a3m-router/discussions) |
| 208 | +- [Changelog](CHANGELOG.md) |
251 | 209 |
|
252 | 210 | --- |
253 | 211 |
|
254 | | -## License |
| 212 | +## The Philosophy (For the Curious) |
255 | 213 |
|
256 | | -[MIT License](LICENSE) |
| 214 | +A3M is built on biological intelligence: evolution solved the routing problem 3 billion years ago. The immune system doesn't use the same response for every pathogen — it routes resources based on threat level. |
| 215 | + |
| 216 | +Same idea here: simple questions get cheap answers. Complex reasoning gets premium models. The router learns from traffic and improves over time. |
| 217 | + |
| 218 | +A3M is 100% open-source, self-hostable, and community-driven. We're not competing with OpenRouter — we're offering a different philosophy: open, decentralized, and yours. |
257 | 219 |
|
258 | 220 | --- |
259 | 221 |
|
260 | | -<p align="center"> |
261 | | - <strong>Built on 3 billion years of biological intelligence.</strong><br> |
262 | | - <a href="https://github.com/Das-rebel/a3m-router">GitHub</a> · |
263 | | - <a href="https://www.npmjs.com/package/adaptive-memory-multi-model-router">npm</a> · |
264 | | - <a href="https://pypi.org/project/a3m-router/">PyPI</a> · |
265 | | - <a href="https://github.com/Das-rebel/a3m-router/discussions">Discussions</a> |
266 | | -</p> |
| 222 | +## ⭐ Star History |
| 223 | + |
| 224 | +[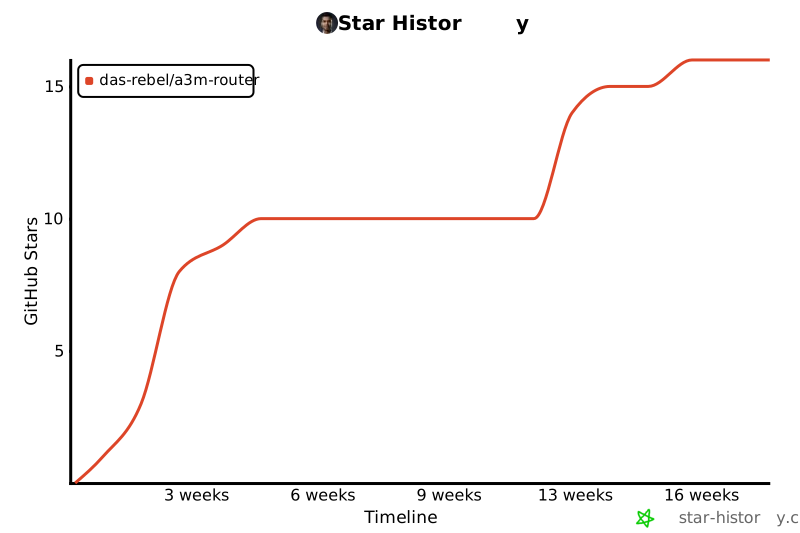](https://star-history.com/#Das-rebel/a3m-router&Timeline) |

0 commit comments