Getting started with Prince in 5 minutes
Except for the latest version of Hadoop, there is no need to install anything else. Just import the prince.py file in your Python program and you can run it with ./python program.py. You can download the prince.py file here.
If you need help on how to get and install Hadoop, I recommend Michael Noll’s excellent tutorial, available here.
Prince is a reference to The Little Prince, a novel written by Antoine de Saint-Exupéry and published in 1943. In the novel, there is a very unusual illustration by Saint-Exupéry of a snake eating an elephant:
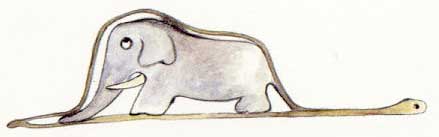
As the logo of Hadoop is an elephant, and the logo of Python is a snake, this depicts exactly what Prince is doing: it’s an elephant in a snake, or Hadoop in Python. You can learn more about The Litte Prince on Wikipedia. The Litte Prince and the related artworks are copyrighted materials owned by N.R.F. Gallimard.
Here is how Prince performs a word count:
import os
import sys
import prince

def wc_mapper(key, value):
    for word in value.split():
        yield word, 1

def wc_reducer(key, values):
    try:                yield key, sum([int(v) for v in values])
    except ValueError:  pass # discard non-numerical values

if __name__ == "__main__":
    prince.init() # Always call prince.init() at the beginning of a program
    prince.run(wc_mapper, wc_reducer, 'input_file', 'output_file', inputformat='text', outputformat='text')
    file = prince.dfs_read(count + '/part*') # Read the output file and print it
    print file
And then as the hadoop user, and with prince.py in the current working directory we simply do:
hadoop@prince$ python wordcount.py
More examples can be found here, including a Dijkstra’s single source shortest path.
init()
Method to call at the beginning of all your programs.
prince.run(wc_mapper, wc_reducer, 'input_file', 'output_file', inputformat='text', outputformat='text')
Run an Hadoop task with the specified Python mapper and reducer methods.
lines = dfs_read('input_file')
Reads the content of a file on the DFS.
get_parameters()
Method callable from the mapper and reducer methods to get parameters passed by the run() method.
You can find more details about these four methods in the Prince API Reference.
- Always start with init(). Make sure you call prince.init() before you do anything else in your program.
- Do not use print in mappers and reducers. Standard input and output are used to carry information between your methods and Hadoop Streaming. If you print some message or value, it will be written to the standard output, and be considered by Hadoop as a pair of (key, value) and will alter your computations.
- Have all mappers and reducers in local name space. All your mapper and reducer methods must be accessible in the name space of your program. This means that they either have to be defined in the same file as your program, or they have to be imported with ‘from imported_file import method’. If you choose the import solution, then you need to make your imported files accessible. This is explained in the next bullet.
- Make all imports accessible. If you import external libraries or other Python files, either make sure that they are accessible in the path of every node of your cluster, or add all necessary Python files to the ‘files’ argument of the run() method. This is particularly important if you import mappers and reducers from a file. See the example import count in the repository for more details about that, and have a look at the Prince API Reference to learn about the ‘files’ argument.
- Make all used files accessible. If you use a file in your computation, you must add this file to the ‘files’ option too.
- Avoid global variables. Keep in mind that Hadoop will start multiple processes with your program, on the same node or different nodes. As the memory spaces of processes are separated by definition, global variables make no sense. Of course, you can use global variables if you wish to, but modification to these variables will remain local to the map or reduce process being executed.
- Time for a coffee break. Do not expect to have awesome computation speed, since it is Python over Java. For performance, prefer Java to Python. But for learning purposes and fast coding, it is nice to have Python.
- The Parallel Dimension Debugging Syndrome. The PDDS, or Parallel Dimension Debugging Syndrome, is what happen when you send your program into a black hole. This is exactly the case with Hadoop: once Hadoop starts mapping or reducing with your Python method, you have no control over what is happening, and you cannot see the raised exceptions and error messages. A solution to that is currently being addressed, and will be available some day (I don’t know when exactly, but I can tell you that this is going to be on a Wednesday). Debugging in a parallel dimension can be very hard sometimes, but do not get frustrated. Here are some debugging tips for coding with Python on Hadoop.
Download Prince, use the API, enjoy and give me feedback. There are tons of cool applications for the MapReduce paradigm, so go find one and solve it with the fun of Python. Here is what you can do now:
- Home page
- Browse the code
- See examples
- Prince API Reference
- Debugging tips
- The Little Prince on Wikipedia
