
TRL is a full stack library where we provide a set of tools to train transformer language models with methods like Supervised Fine-Tuning (SFT), Group Relative Policy Optimization (GRPO), Direct Preference Optimization (DPO), Reward Modeling, and more. The library is integrated with 🤗 transformers.
📜 Training beyond 1M tokens: A new long context guide walks through the four things that break as sequences grow — the loss, the positions, the activations and the memory of a single GPU — and ends on an example that trains Qwen3-8B on million-token sequences on one 8-GPU node.
Below is an overview of TRL trainers, organized by maturity and method type.
You can also explore TRL-related models, datasets, and demos in the TRL Hugging Face organization.
Learn post-training with TRL and other libraries in 🤗 smol course.
The documentation is organized into the following sections:
- Getting Started: installation and quickstart guide.
- Conceptual Guides: dataset formats, training FAQ, and understanding logs.
- How-to Guides: reducing memory usage, speeding up training, distributing training, etc.
- Integrations: DeepSpeed, Liger Kernel, PEFT, etc.
- Examples: example overview, community tutorials, etc.
- API: trainers, utils, etc.
Published on May 27, 2026
Shipping a Trillion Parameters With a Hub Bucket: Delta Weight Sync in TRL

Published on March 31, 2026
TRL v1: Post-Training Library That Holds When the Field Invalidates Its Own Assumptions
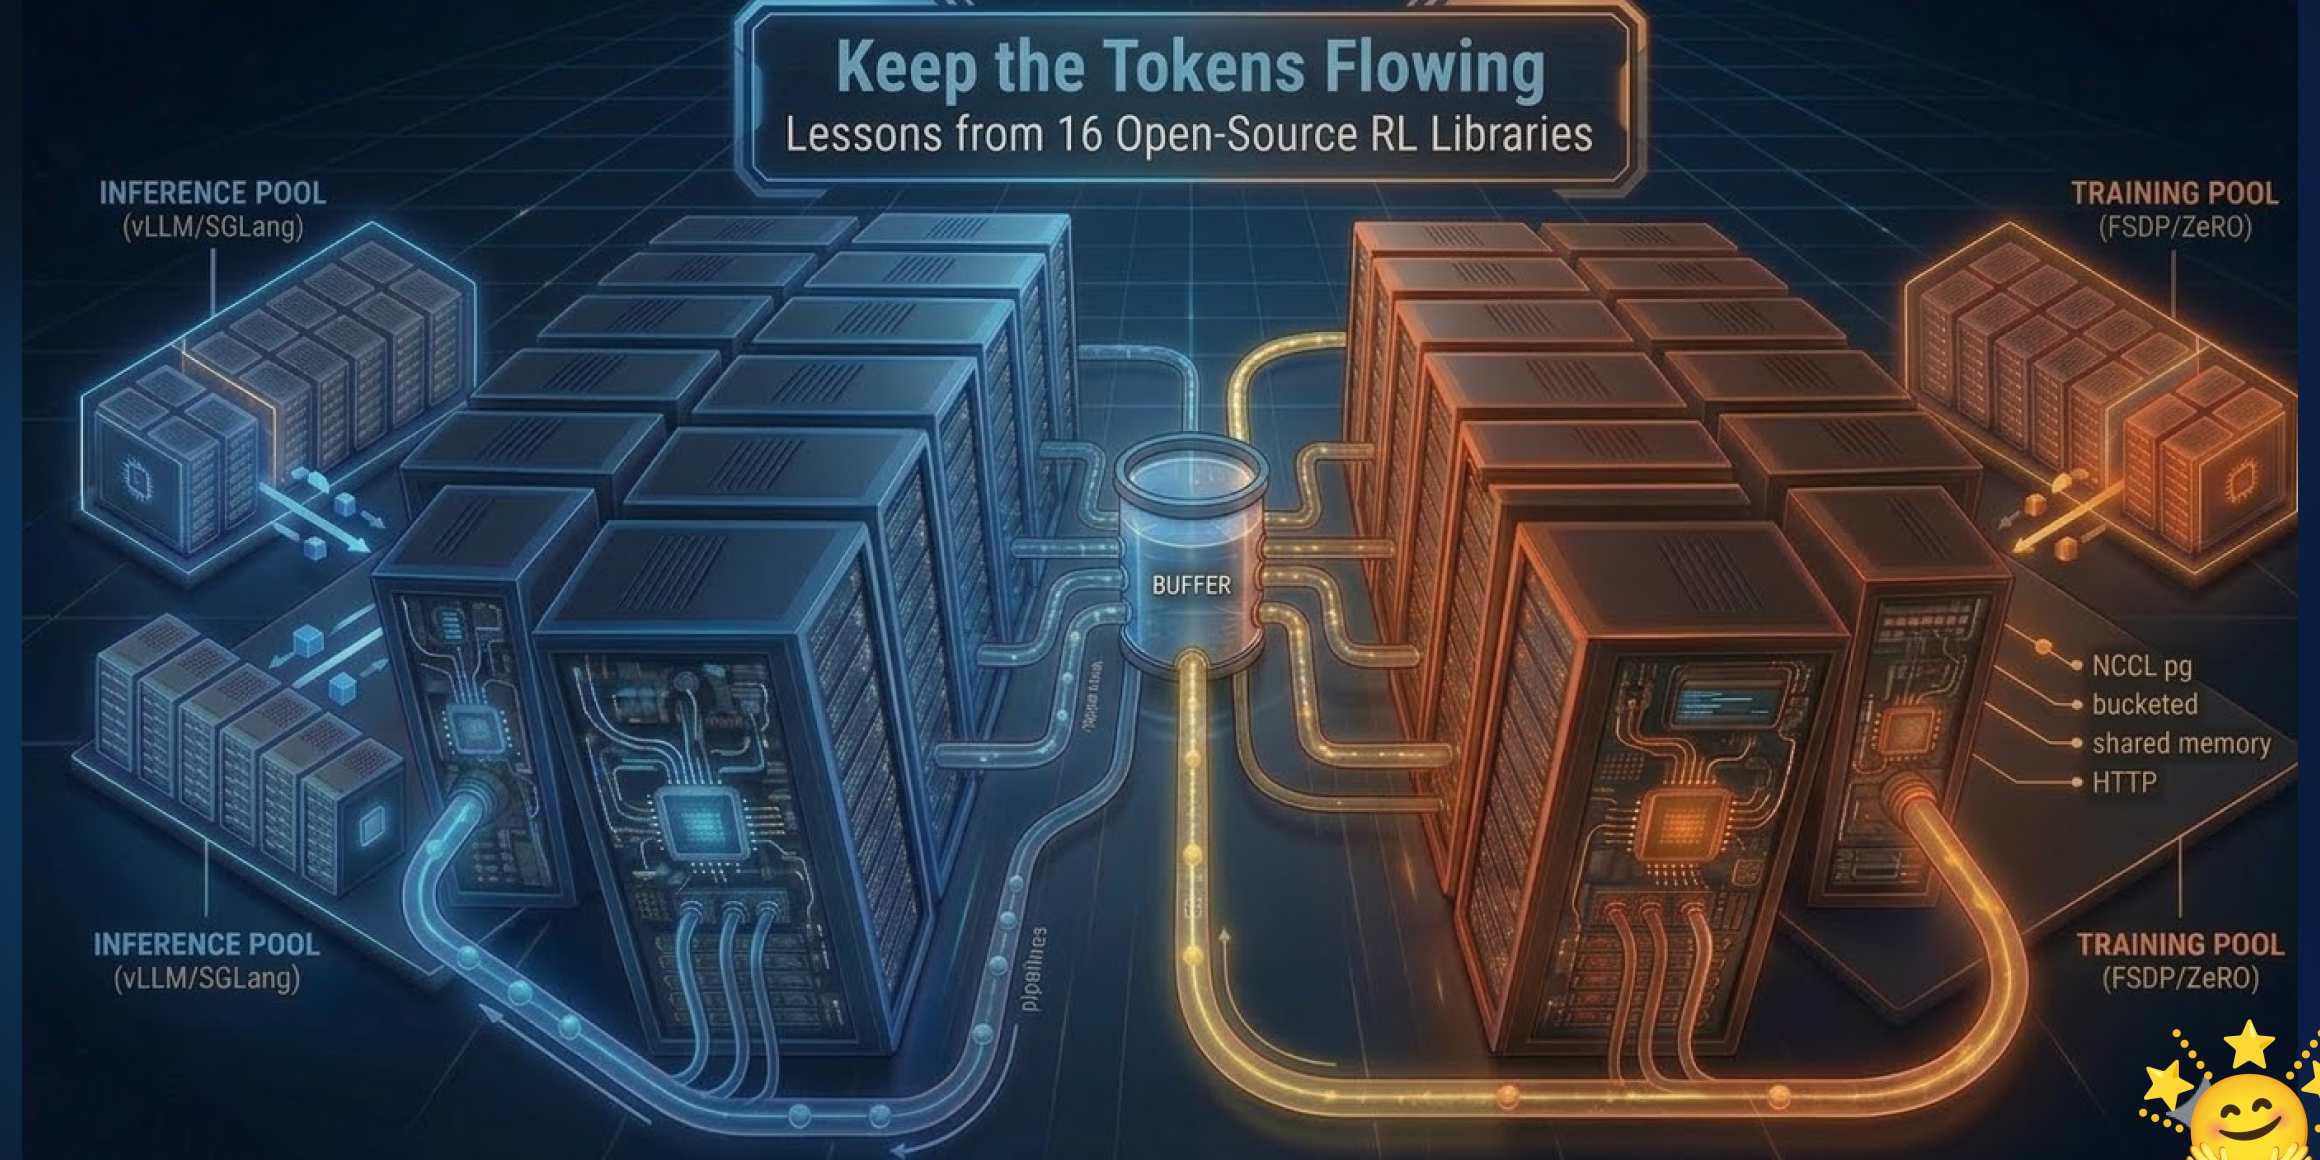
Published on March 10, 2026
Keep the Tokens Flowing: Lessons from 16 Open-Source RL Libraries
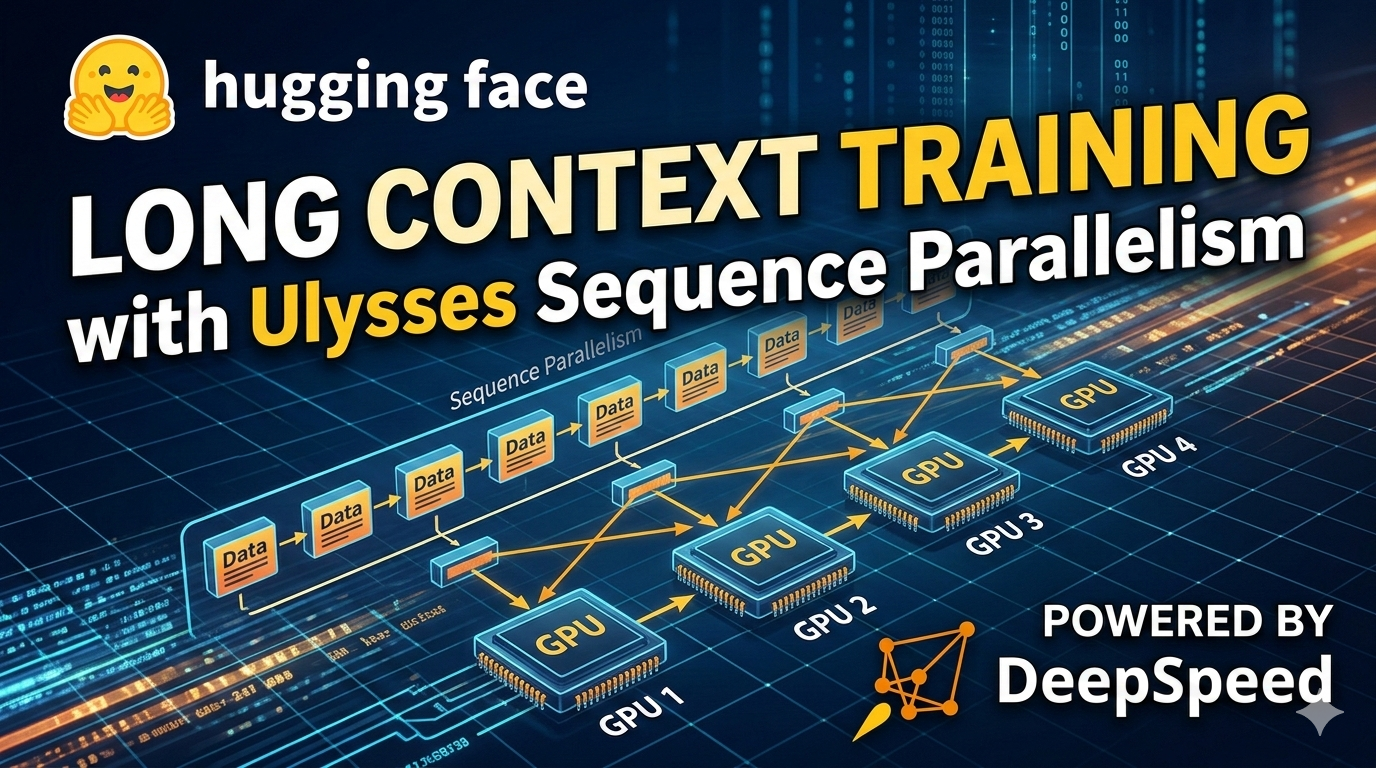
Published on March 9, 2026
Ulysses Sequence Parallelism: Training with Million-Token Contexts
Published October 23, 2025
Building the Open Agent Ecosystem Together: Introducing OpenEnv
Published on August 7, 2025
Vision Language Model Alignment in TRL ⚡️
Published on June 3, 2025
NO GPU left behind: Unlocking Efficiency with Co-located vLLM in TRL
Published on May 25, 2025
🐯 Liger GRPO meets TRL
Published on January 28, 2025
Open-R1: a fully open reproduction of DeepSeek-R1
Published on July 10, 2024
Preference Optimization for Vision Language Models with TRL
Published on June 12, 2024
Putting RL back in RLHF
Published on January 10, 2024
Make LLM Fine-tuning 2x faster with Unsloth and 🤗 TRL
Published on September 29, 2023
Finetune Stable Diffusion Models with DDPO via TRL
Published on August 8, 2023
Fine-tune Llama 2 with DPO
Published on April 5, 2023
StackLLaMA: A hands-on guide to train LLaMA with RLHF
Published on March 9, 2023
Fine-tuning 20B LLMs with RLHF on a 24GB consumer GPU
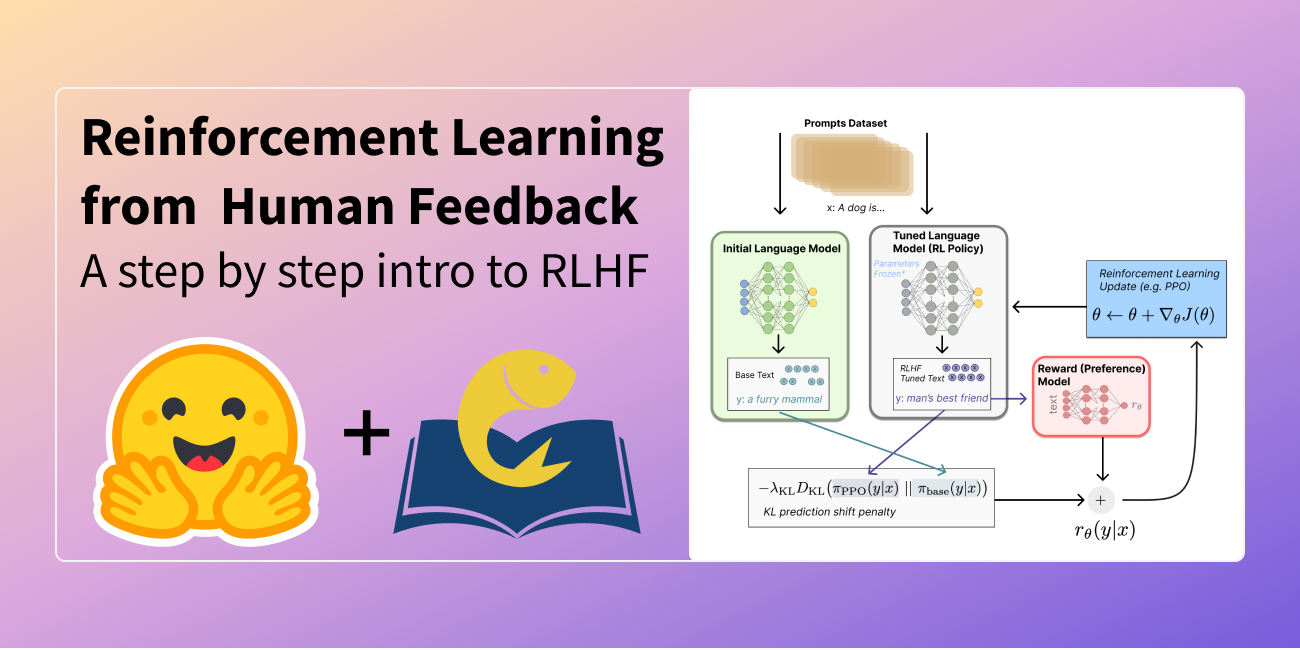
Published on December 9, 2022
Illustrating Reinforcement Learning from Human Feedback
