
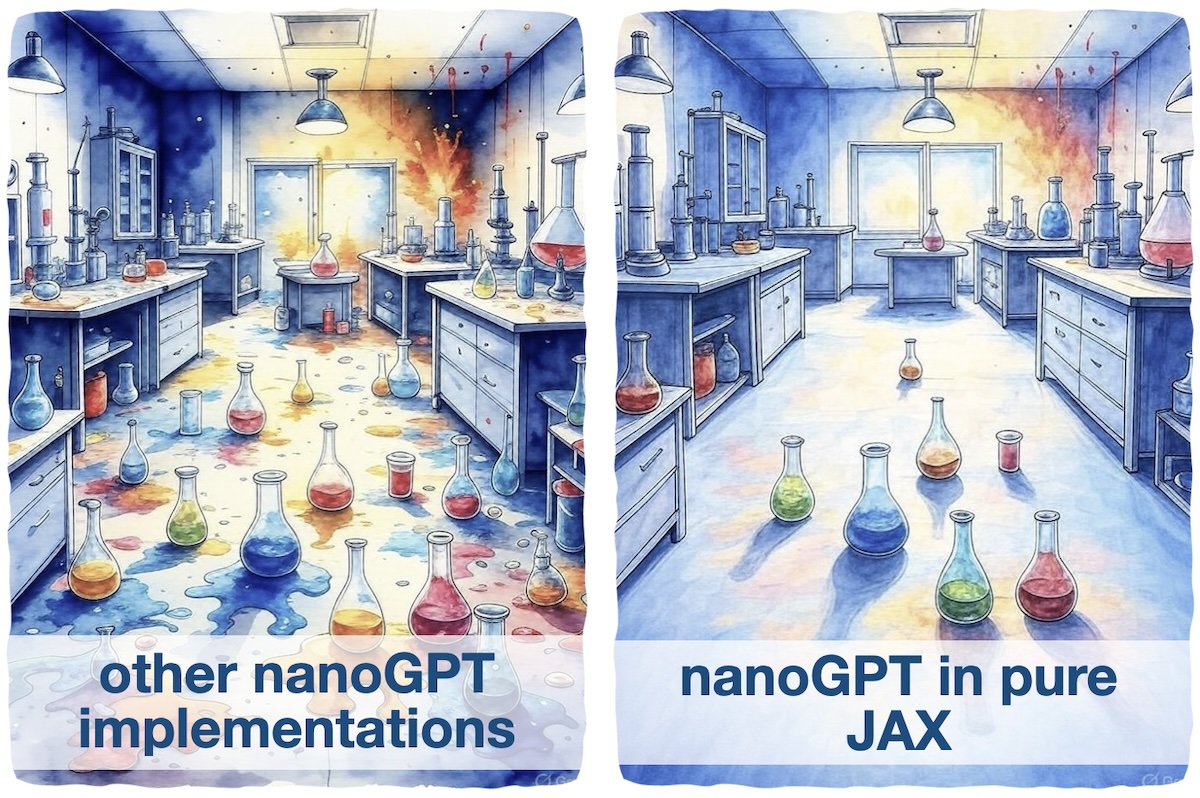
The purpose of this repository is mostly documenting my own learning progress on recent developments in AI. I first wanted to learn more transformers and the process of training LLMs and at the same time I wanted to learn about JAX. Give these goals a reasonable project was to re-implement nanoGPT in pure JAX. In the process I have found that I typically ended up with much cleaner code, compared to PyTorch. So I decided to split the code base up into smaller reusable and more modular parts and release it. Now it can be used for educational purposes, or as a clean and hackable starting point for small scale experiments on modified architectures, training strategies or experiments in interpretability. I think cooking a new experiment needs to start from a clean lab, so happy cooking!
Note: if you need minimal production grade implementations of LLMs you might rather want to check out official JAX LLM examples or for large scale experiments and training checkout Levanter, which is based on Equinox.
This repositiry comes with mutiple pre-defined environments in a pixi.toml file. This makes it very covenient to run the model in CPU, GPU and even TPU (soon...) environments.
To get started, you first install pixi using:
curl -fsSL https://pixi.sh/install.sh | shAnd then proceed with one of the options:
To train a small transformer model with character level encoding on the "Tiny Shakespeare" dataset you can use:
pixi run download --dataset shakespeare
pixi run --environment prepare prepare --dataset shakespeare --encoding char --shard-size 1000000 --shards-val 1
pixi run --environment cpu train train-shakespeare-char
pixi run --environment cpu sample --init-from resume --sampler.max-new-tokens 500 --sampler.num-samples 5
The workflow always consists of those four steps. The training should finish in <2 minutes on a M1 type machine.
All the sub-commands have a --help option which shows you the available configuration options.
To train a GPT2 124m model on the Fineweb10b dataset on two GPUs you can use for example:
pixi run download --dataset fineweb_10b
pixi run --environment prepare prepare --dataset fineweb_10b
pixi run --environment gpu train train-fineweb-10b-on-8-gpus
pixi run --envrionment gpu sample --init-from resume --sampler.max-new-tokens 500 --sampler.num-samples 5
nanogptx supports a simple SPMD (single program multiple data) distribution strategy, meaning groups of batches are evaluated in parallel on the configured devices.
Here are some of the features of the nanogptx implementation:
- 🗄️ Hierarchical configuration: I do like hierarchical configuration as long as it is not too deep (3-4 levels max). The confiuration system is based on TOML and dataclasses, combined with JAX pytree operations and dacite for serialization and deserialization. The configuration requires setting defaults and on I/O it does type coercion to the default type, to catch errors early.
- 💻 CLI: after careful consideration I have decied to support a CLI via tyro. The code overhead is minimal, as all the configuration is in dataclasses anyway. And tyro offers a nice default interface as well as nested commands.
- ✨ Abstract evaluation and lazy initialization: I think it is useful to not fully instantiate a model on creation, but rather instantiate an abstract description of the array shapes, dtypes and shardings. This allows for an abstract evaluation which catches shape, dtype and sharding errors early without using any flops.
- 🗃️ Minimal provenance: The implementation supports minimal provenance of model configs, datasets and training. This includes logging of which batch is trained on, saving configs in model files and verifying data hashes.
- 🐍 Support for Pixi enviromments: this repository includes a
pixi.tomlwith pre-defined environments for many scenarios such as CPU, CPU and even TPU. I have also tried to support MPS, viajax-metal, but ran into multiple issus with missing support for operations. - 💯 Sharding strategies: Currently only SPMD is supported, other strategies might follow...
- 📚 Data preprocessing pipeline: A minimal function based pre-processing pipeline for tokenization and custom document cleaning / pre-processing.
- 📇 Logging: just as the original nanoGPT this project uses WandB for logging. I have considered alternatives (especially local solutions), but found other solutions introduced more complexity with fewer features.
This repository can be used as template for your own small to mid-scale research and educational projects. You can explore different training strategies,
modified architectures etc. As everything is in pure JAX, you can modify any small component in the model, without the need of implementing whole new layers.
nanogptx still provides the whole scalable infrastructure.
There is a dedicated option and environment for profiling available. The approch follows the programmatic capture section in the JAX docs. An you can enable it using:
pixi run --environment cpu train train-shakespeare-char --training.profile.record-trace
pixi run --environment gpu train train-fineweb-10b-on-8-gpus --training.profile.record-trace
The profiles will be stored in .profile/<run name>/ and can be opened using e.g. xprof:
pixi shell --environment tensorboard
xprof --logdir=.profile/<run name>/ --port=6006If you would like to add a new config, I would suggest to start from the config/default.toml file, which includes all available configuration options. Copy the file to a new name and edit as needed. As long as the file is in the config/ folder it will be automatically discovered and validated.
If you would like to add a new dataset follow these steps:
- Add a new entry to the
DatasetEnuminsrc/utils.pywith a short identifier of your dataset - Add the download urls in the registry in
src/download.py, decompressing / unzip / untar should also happen at this step - Add a custom read function in
src/prepare.pyas needed and add it to the registry
Thanks to @fcrespo82 for the names list from the Ubuntu Name generator. Thanks to @rdyro for the help on initial performance issues.