Self-hosted, multi-modal AI server for your own GPU — one command, nothing to compile.


Chat LLMs · Vision · Text-to-speech · Image generation — all behind one OpenAI-compatible endpoint.
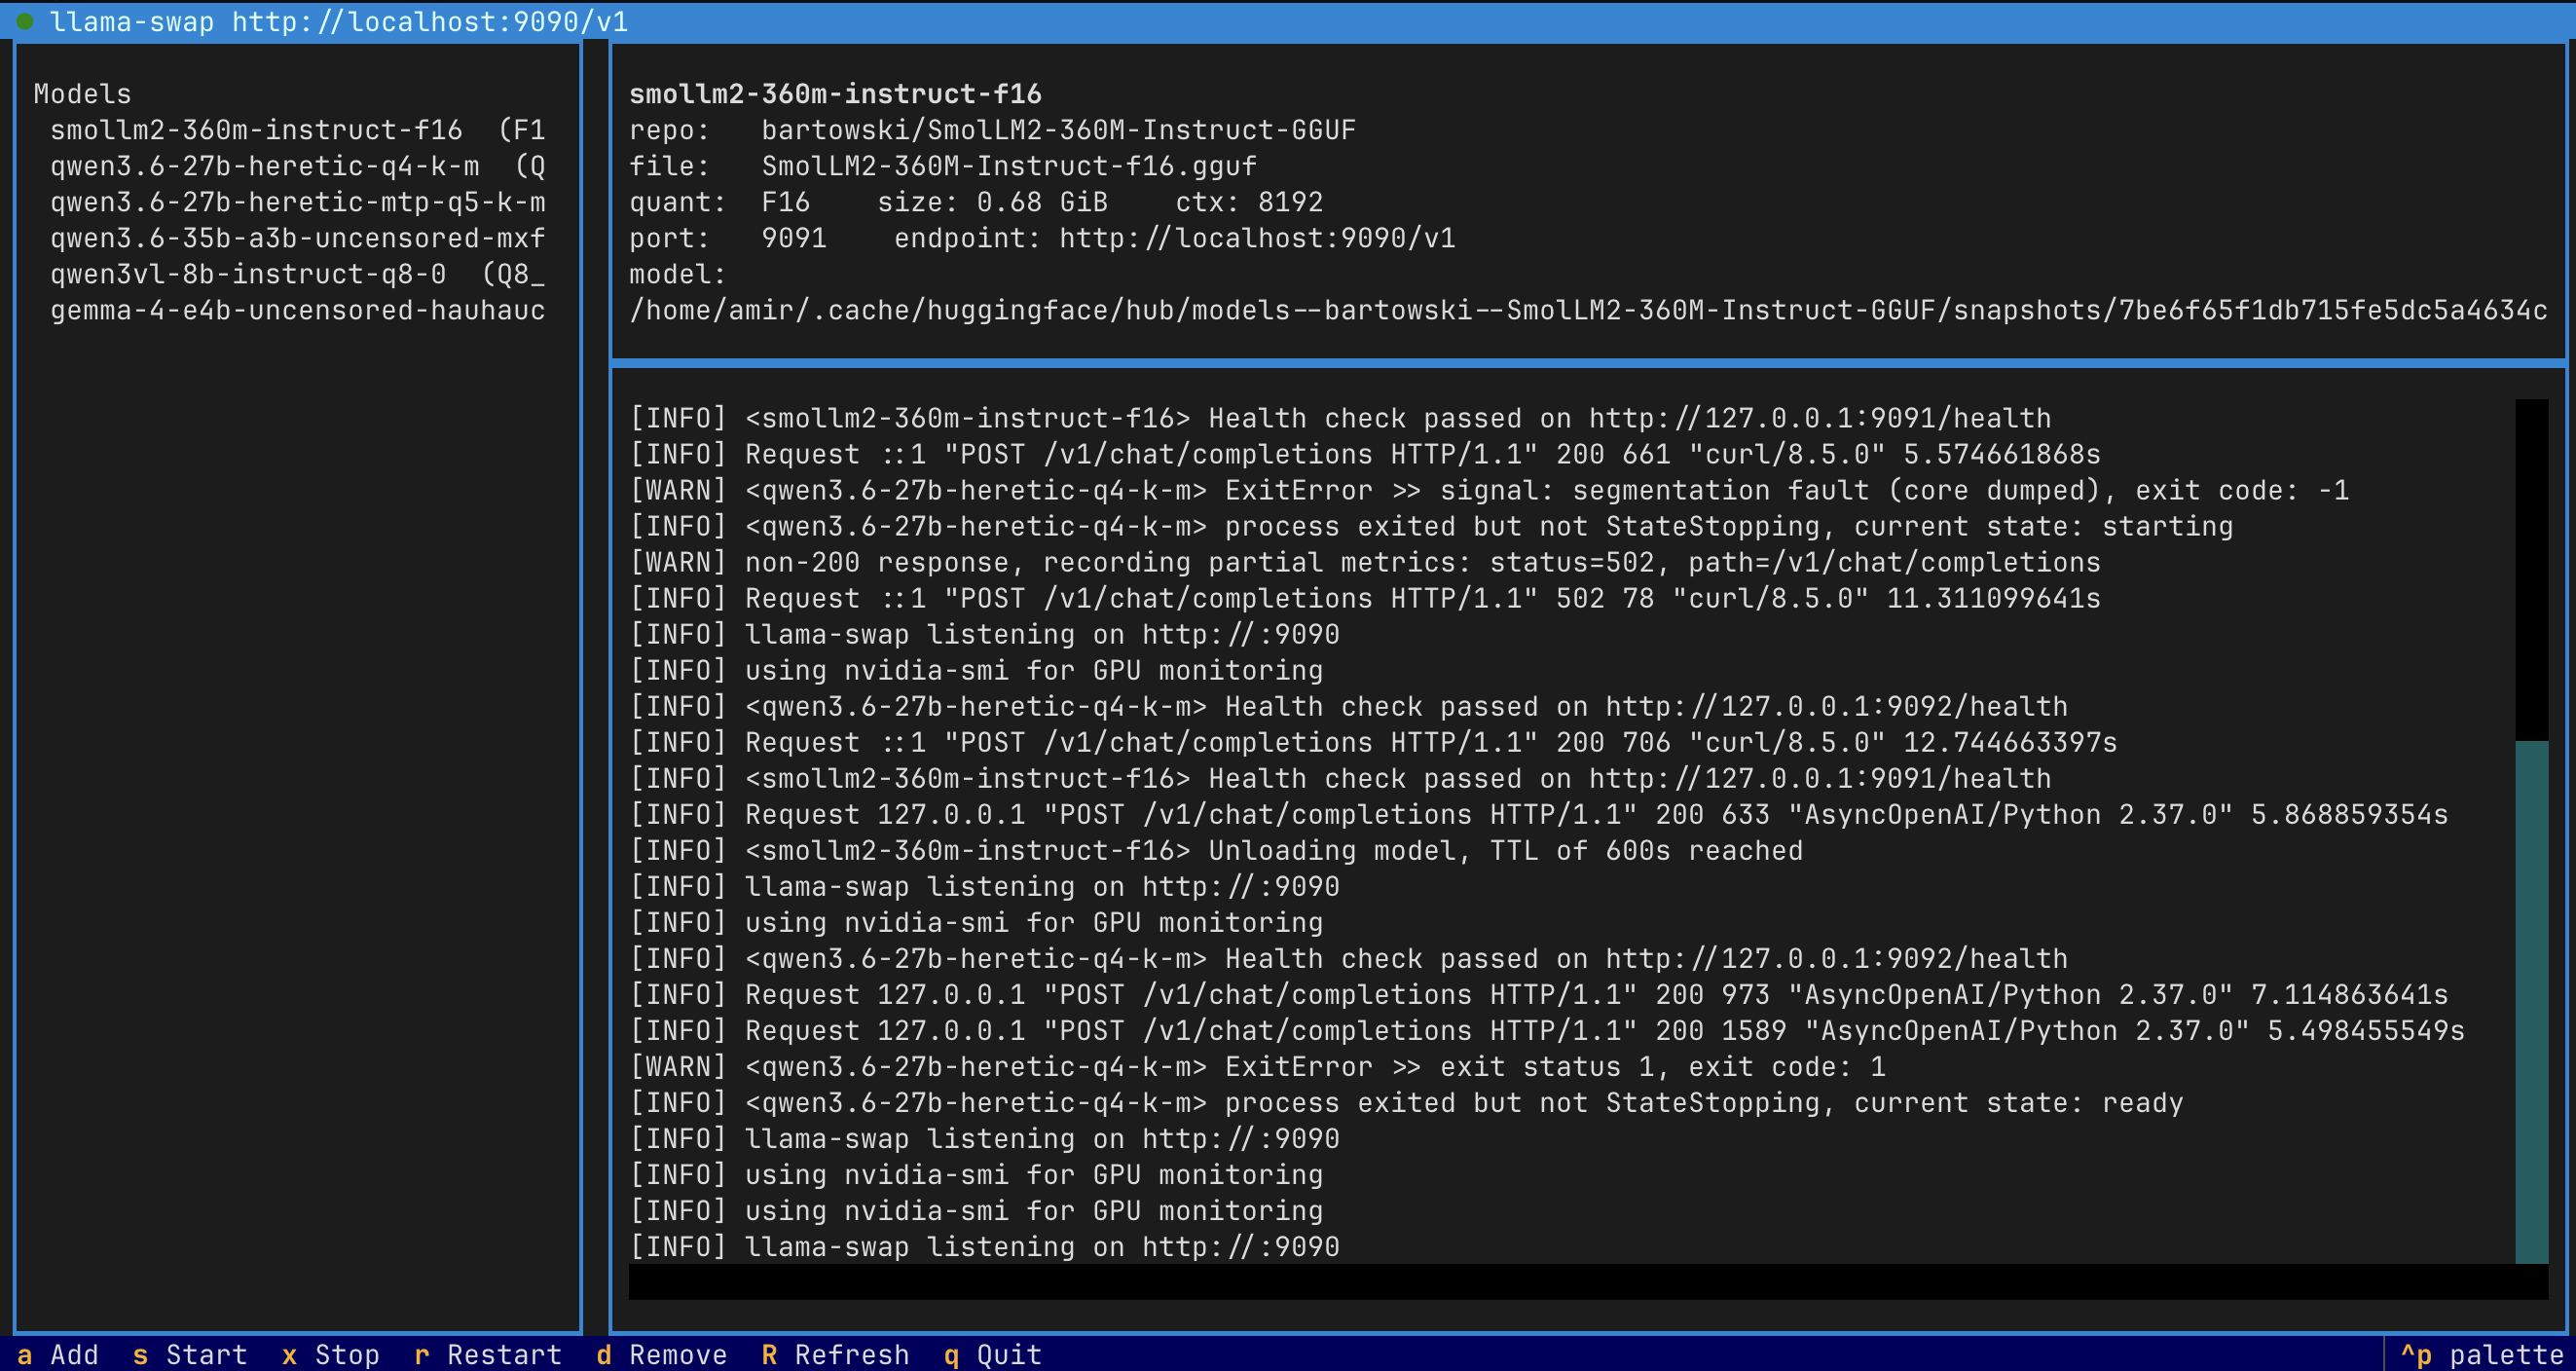
inferhost turns any GPU machine into a private, local AI inference server. It wraps llama.cpp and stable-diffusion.cpp behind a single OpenAI-compatible API, pulls the official upstream binaries for your hardware (no compiling, no CUDA toolkit), auto-downloads the right model files when you paste a Hugging Face link, and hot-swaps models in and out of VRAM so one GPU can serve a large language model, a text-to-speech voice, and an image-generation pipeline side by side. Everything is driven from a keyboard dashboard (TUI) or a headless CLI, configured through a single optional .env file.
If you are searching for a self-hosted alternative to cloud AI APIs — a local LLM server with vision (multimodal) support, speech synthesis, and Stable Diffusion / Flux image generation on the same OpenAI-compatible gateway — inferhost is one pip install away.
uv tool install inferhost      # or:  pipx install inferhost  /  pip install inferhost
inferhost                      # opens the dashboard — press 'a' to add a model
That is the whole setup. The first launch fetches the runtime binaries automatically. To add a model, press a and paste a Hugging Face repo — inferhost lists the files, recommends the best quantization for your VRAM, downloads what is needed (including companions such as vision projectors, vocoders, VAEs, and text encoders), and serves it. Then call it like OpenAI:
| Chat / LLM | Text-to-speech | Image generation |
|---|---|---|
pasteQwen/Qwen2.5-7B-Instruct-GGUF |
pastehexgrad/Kokoro-82M |
pasteOlegSkutte/sdxl-turbo-GGUF |
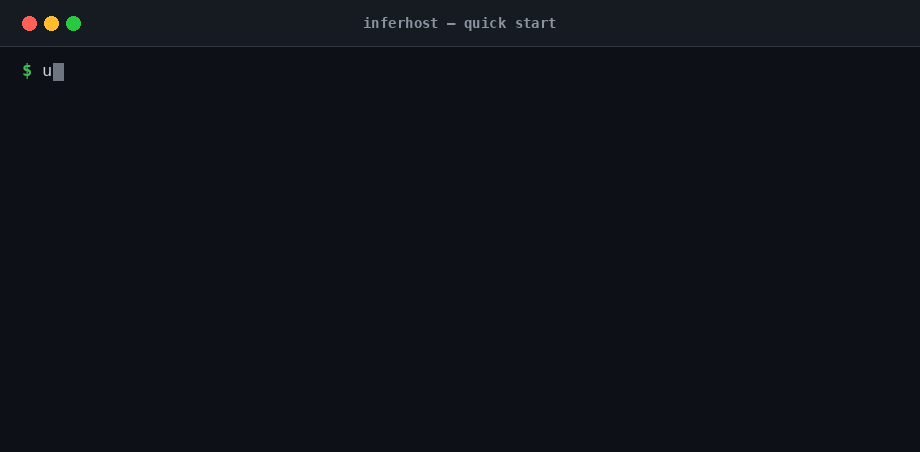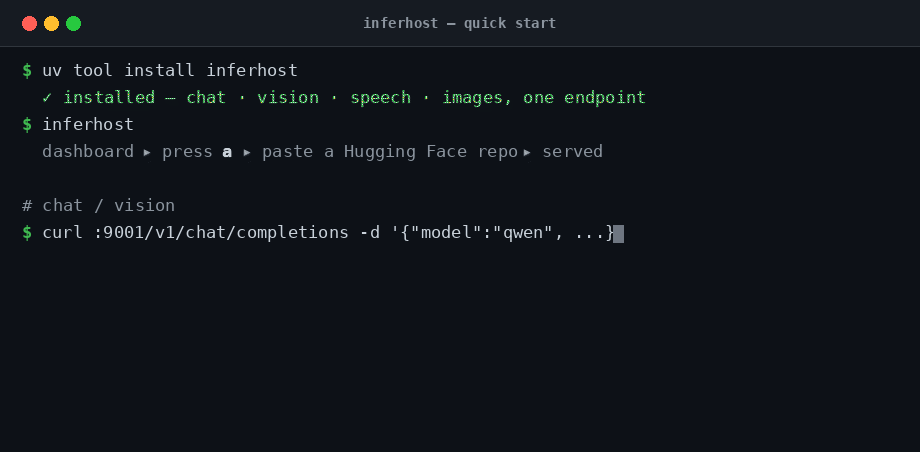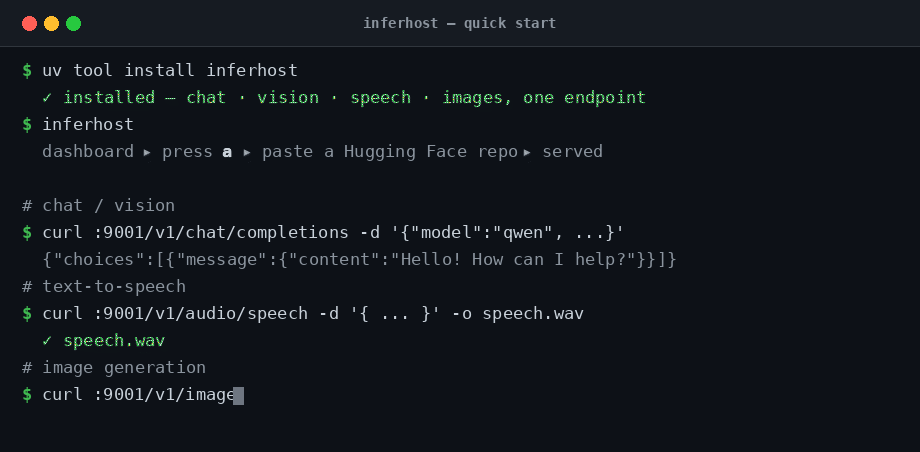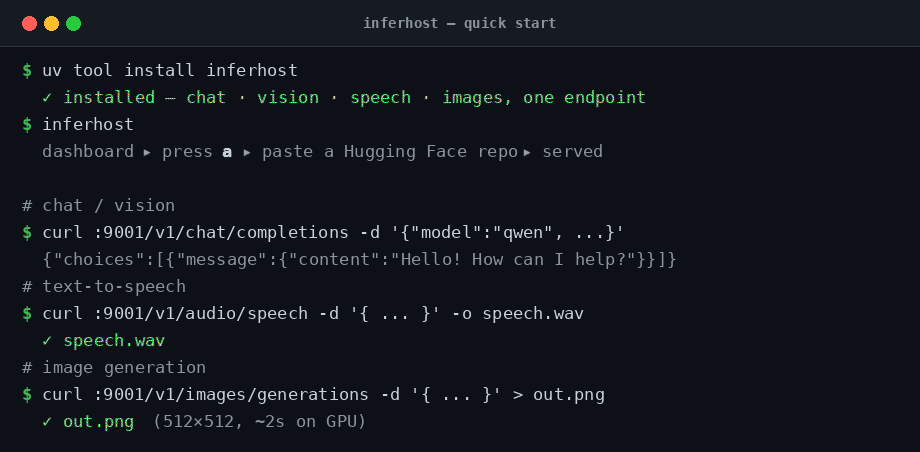
# Chat  ->  /v1/chat/completions
curl http://localhost:9001/v1/chat/completions -H 'Content-Type: application/json' \
  -d '{"model":"<name-from-dashboard>","messages":[{"role":"user","content":"Hello!"}]}'

# Speech  ->  /v1/audio/speech   (returns WAV)
curl http://localhost:9001/v1/audio/speech -H 'Content-Type: application/json' \
  -d '{"model":"<name>","input":"Hello from inferhost.","voice":"af_heart"}' --output speech.wav

# Image  ->  /v1/images/generations   (returns base64 PNG)
curl http://localhost:9001/v1/images/generations -H 'Content-Type: application/json' \
  -d '{"model":"<name>","prompt":"a red apple on a table","size":"512x512"}' \
  | jq -r '.data[0].b64_json' | base64 -d > out.png
Everything lives on http://localhost:9001/v1 — point any OpenAI client at it (OpenAI Python SDK, LangChain, Open WebUI, LibreChat, Continue, Cursor, or your own app). The model name is whatever shows in the dashboard.
- One endpoint, every modality — chat, vision, speech, and images on the same OpenAI-compatible
:9001. No per-model servers to wire up. - Nothing to compile, and never stale — official
llama-server/sd-serverbinaries are pulled from upstream for your hardware: NVIDIA and AMD GPUs (Vulkan), AMD ROCm, Intel SYCL, Apple Silicon (Metal), and plain CPU. If a model's architecture is newer than the llama.cpp on disk, inferhost notices and fetches a build that supports it, so a model released this week loads on a box installed last year.inferhost updatedoes it on demand. - Paste a link, it figures out the rest — recommends the best GGUF quantization for your VRAM, handles multi-part (sharded) GGUFs, and for multi-file image models (Flux, Z-Image, Qwen-Image) auto-downloads the matching VAE and text encoders from known-good repos.
- One GPU, many models — llama-swap lazy-loads and hot-swaps models in and out of VRAM on demand, so a 24 GB card can serve a 27B LLM and Flux image generation without manual juggling.
- TUI or headless — drive everything from a keyboard dashboard, or run
inferhost start/stop/statuson a remote server with no terminal attached.inferhost autostart oninstalls a systemd user unit so the whole stack comes back by itself after a reboot. - Fast by default — speculative decoding (DFlash draft models, MTP/NextN, n-gram), KV-cache quantization, MoE expert CPU offload, and honest context windows, all tuned automatically and overridable per model or from
.env. - Private by design — models, weights, and prompts never leave your machine. No accounts, no telemetry, no cloud dependency.
| Modality | Models | How |
|---|---|---|
| Chat / LLM | any GGUF language model — Qwen, Llama, Gemma, DeepSeek, Mistral, and more, including NVFP4/MXFP4 block-scaled 4-bit builds, 2-bit ternary builds (Ternary Bonsai), and sharded multi-part GGUFs | paste repo, pick quant |
| Vision (multimodal) | any GGUF vision model with an mmproj projector — Qwen3-VL, DeepSeek-OCR, Gemma vision variants |
projector auto-detected and downloaded |
| Speech (TTS) | Kokoro-82M, Orpheus-3B (incl. finetunes), OuteTTS | paste repo — hexgrad/Kokoro-82M resolves to its ONNX weights + voices automatically; Orpheus repos (e.g. unsloth/orpheus-3b-0.1-ft-GGUF) fetch their SNAC decoder automatically; OuteTTS vocoders are auto-detected |
| Image — single-file | Stable Diffusion 1.5, SDXL (incl. Turbo) | paste repo, pick file |
| Image — Flux.1 | schnell / dev | auto-fetches VAE + CLIP-L + T5XXL |
| Image — Flux.2 Klein | incl. Bonsai-Image (1-bit) | auto-fetches VAE + Qwen3-4B |
| Image — Z-Image | Z-Image-Turbo | auto-fetches VAE + Qwen3-4B |
| Image — Qwen-Image | Qwen-Image / Qwen-Image-Edit | auto-fetches VAE + Qwen2.5-VL + mmproj |
All image families above were verified end-to-end on a Vulkan GPU (SDXL-Turbo ~2 s, Flux-schnell ~4 s, Bonsai ~2 s, Z-Image-Turbo ~11 s, Qwen-Image-Edit via /v1/images/edits).
Every knob below is set to a sensible default automatically and can be overridden per model from the dashboard's Configure screen (or globally via .env):
- Speculative decoding, three lanes — attach a DFlash block-diffusion draft model to a supported target, use MTP / NextN prediction heads (auto-detected from the GGUF metadata), and stack the model-free n-gram lane on top for extra decode speed.
- KV-cache quantization — q8_0 key/value cache compression by default, per-model override, with automatic fallback when a binary build does not support a cache type.
- VRAM-aware quant picker — the add screen probes your GPU and marks the best-fitting quantization before you download anything.
- Model pinning and hot-swap — pin a model to keep it resident in VRAM; unpinned models load on first request and unload after an idle TTL. A watcher daemon reloads pinned models automatically after evictions, crashes, or reboots — as soon as the GPU is idle again, the pin comes back. Pinning works for TTS too: a pinned Orpheus model stays in VRAM like a chat model, a pinned Kokoro model is pre-loaded by the TTS daemon at startup.
- Mixture-of-Experts offload — push MoE expert layers to CPU (
--n-cpu-moe) to fit large sparse models such as Qwen3.6-35B-A3B on a single consumer GPU. - Reasoning control — per-model thinking mode (on / off / auto), reasoning budget, and reasoning effort (low / medium / high) for templates that grade how hard the model thinks.
- Per-model vision toggle — trade image input for an attached DFlash draft on vision models, and switch back at any time (MTP needs no trade — it runs with vision on).
- Honest context windows — the context you configure is what a single request actually gets: clamped to the GGUF's real trained context (read from the file header), and scaled up for parallel slots so concurrency never silently shrinks the window. What the gateway advertises always matches what's served.
- CPU threads and memory locking — per-model
--threadsand--mlockfor latency-sensitive deployments.
DFlash speeds up a large target model by attaching a small z-lab block-diffusion draft model that proposes several of the target's next tokens per step, which the big model verifies in one pass — the target's quality at a fraction of the wall-clock time. It is a per-model attachment (like a vision projector), served by the same upstream llama-server (build b10658 or newer) — nothing extra to compile.
Press f on a highlighted chat model and, if it has a known pairing, the right community draft downloads and wires itself up. Or use Configure → Suggest / Browse / Clear for a progress bar and manual repo entry — pasting an official z-lab draft repo (raw safetensors, no GGUFs) into Browse auto-redirects to its paired GGUF conversion when one is known. Configure also exposes an explicit Off / MTP / DFlash selector and a method-specific draft-token depth, so an attached draft can stay downloaded while you benchmark it against built-in MTP.
| Target family | Draft repo |
|---|---|
| Qwen3.6-27B / 35B-A3B (MoE) | Alittlehammmer/*-DFlash-GGUF-llama.cpp |
| Gemma-4-31B / 26B-A4B (MoE) | Alittlehammmer/*-DFlash-GGUF-llama.cpp |
| Gemma-4-12B | williamliao/gemma-4-12B-it-DFlash-GGUF |
| Qwen3.5-27B / Qwen3-Coder-30B-A3B (MoE) | AtomicChat/*-DFlash-GGUF |
| Qwen3.5-9B | Anbeeld/Qwen3.5-9B-DFlash-GGUF |
- Thinking caveat: DFlash acceptance drops sharply (~5-14%) with reasoning on — run the target with reasoning off for the full speedup. inferhost warns when a draft is attached to a model whose reasoning resolves to
on. - Vision caveat: an external DFlash draft cannot run on a model with a vision projector (
--mmproj) — an upstreamllama-serverlimit. inferhost disables just that lane and falls to the next one down: MTP if the GGUF has the heads (unaffected by vision — it drafts inside the target's own context), otherwise the model-free n-gram lane. Images always work. To get DFlash instead of images, set Vision / image input tonoin the model's Configure screen — the model serves text-only and DFlash switches back on (flip it back any time; the projector stays downloaded). - VRAM: the draft is co-resident with the target (usually well under 2 GiB) and folded into the VRAM/pin-feasibility estimate automatically.
- Checkpoint compatibility: a DFlash draft is trained against a particular target checkpoint. A same-size fine-tune may load successfully but accept too few tokens to be faster; compare it with MTP rather than assuming the family name is enough.
- MoE targets (
...-A3B/...-A4B) are already cheap per step, so DFlash buys a smaller speedup than on a dense model of similar total size. - On a
llama-serverolder than b10658, inferhost refreshes a managed binary; custom builds needinferhost update --rebuild— see Usage.
Full guides live in docs (and in the docs/ folder):
- Installation — install, upgrade, uninstall, requirements
- Usage — the dashboard, keyboard keys, and chat / TTS / image / Flux / Z-Image / Qwen-Image walkthroughs
- Configuration — every
.envvariable, KV-cache quant, custom binaries - Troubleshooting — ports, tmux mouse, common errors
Architecture
Your app ──HTTP──▶  LiteLLM gateway        llama-swap (loopback)       llama-server  (chat/vision)
                    :9001 (public)   ──▶    127.0.0.1:9090      ──┬──▶  sd-server     (images)
                                                                  └──▶  inferhost-tts (speech)
- llama.cpp (
llama-server) runs chat/vision inference — official upstream binary, backend auto-detected. - llama-swap fronts the model backends and lazy-loads / hot-swaps them on demand (loopback only). Image models (
sd-server) ride here too, so they swap VRAM with LLMs. - inferhost-tts serves
/v1/audio/speech(started only when a TTS model is registered): Kokoro runs in-process via kokoro-onnx (loads once, stays resident, fast); Orpheus generates its audio tokens onllama-serverbehind llama-swap (so it swaps VRAM with your LLMs and can be pinned like one) and the daemon decodes them via a small SNAC ONNX decoder; OuteTTS goes through llama.cpp'sllama-tts. - LiteLLM is the single always-on public gateway on
:9001, routing each request to the right backend.
The extra engines (llama-tts, sd-server) are fetched automatically the first time you add a model that needs them. Nothing is ever compiled on the host.
Development
The repo ships a run.sh wrapper for source-tree work (end users never need it — they only type inferhost):
git clone git@github.com:amirrouh/inferhost.git && cd inferhost
./run.sh install     # venv + editable install
./run.sh start       # launch the TUI (downloads binaries on first run)
./run.sh status      # headless status
./run.sh stop        # stop daemons
./run.sh update      # re-fetch llama.cpp / llama-swap binaries
./run.sh prune       # list (--yes deletes) unused HF cache models
./run.sh test        # pytest
Run ./run.sh help for the full list.